Skip to content

Smart LLM routing: automatically route to the right model

Send every request to the model that fits the task best, without overpaying for simple work and compromising on complex-work quality.

  • Optimize AI costs on every request
  • Route for quality that fits the task
  • Faster responses, fewer outages
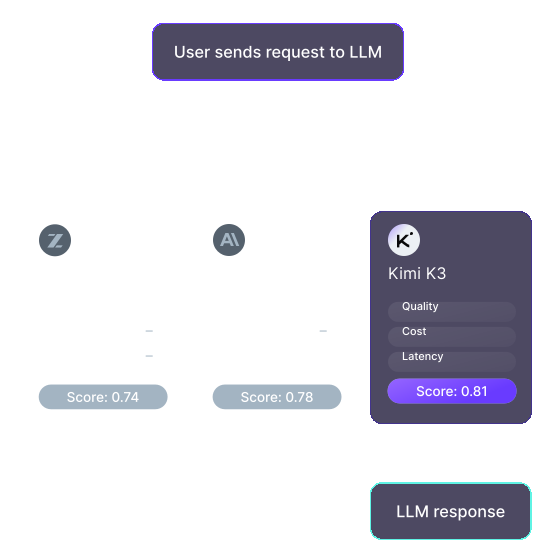
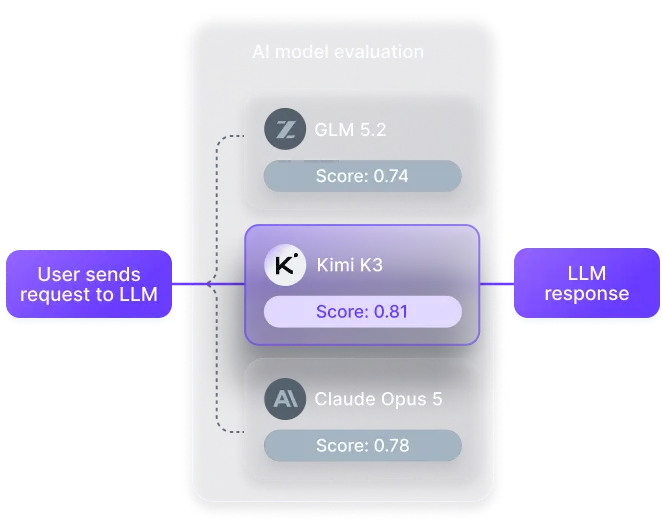
NexEco AI routes each request to the large language model that fits the task best

Chosen by leading engineering teams

Logos of companies that trust NexEco AI

Benefits of Smart LLM routing for your business

Smart LLM routing replaces a single default model – cutting your costs, reducing failed requests, and eliminating the engineering overhead of hand-built routing logic.

Requests are routed to a lower-cost one

Cut costs, not quality

Many LLM workloads vary in complexity – some requests genuinely need a frontier model, and the rest can be handled fine on a lower-cost one. Smart routing draws that line automatically, so you stop paying premium prices for routine work.
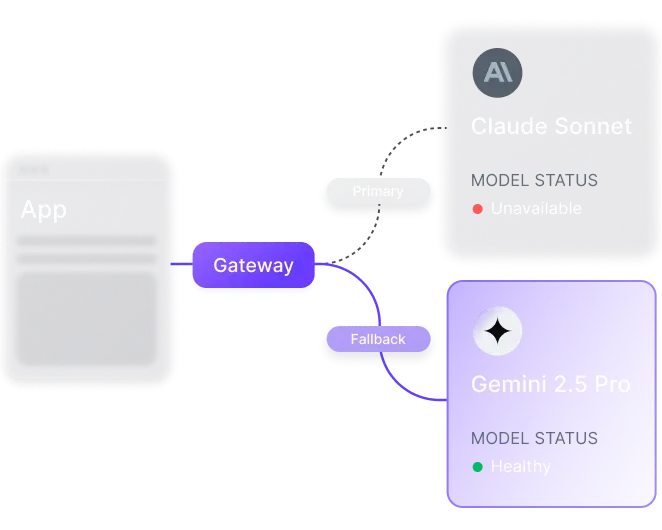
NexEco AI gateway routes requests based on model performance and availability

Improve reliability and performance

Smart LLM routing directs requests based on model performance and availability. If a model slows down or becomes unavailable, traffic can shift to another option, helping maintain faster responses and fewer failed requests.

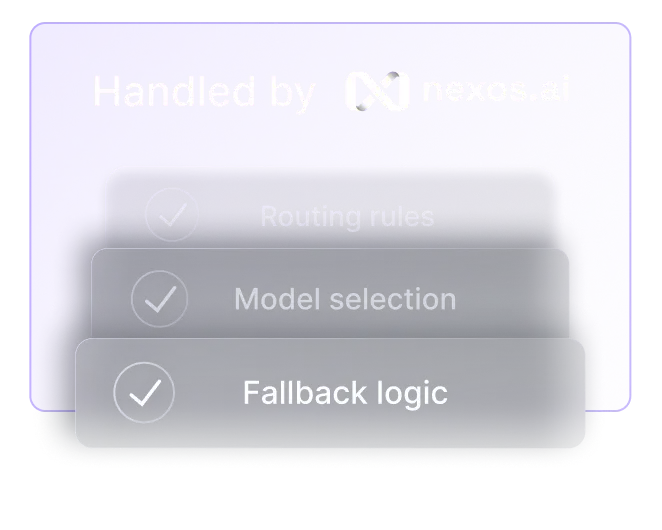
Fallback logic, model selection, routing handled by NexEco AI gateway

No routing logic to build or maintain

Connect to the NexEco AI Gateway and routing is handled for you. No custom logic to write, test, or keep in sync across multiple providers. As your model stack grows, Smart Routing scales with it automatically.

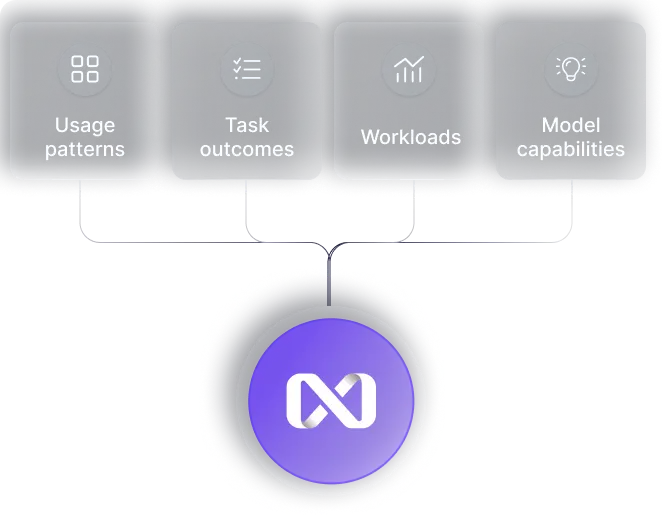
NexEco AI routing system gets smarter over time learning from new patterns and adapting

Continuous learning

The routing system gets smarter over time, learning from new patterns and adapting as tasks, workloads, and model capabilities evolve. This helps keep routing decisions effective as new models emerge and performance changes, without constant manual tuning.

Smart routing is more than choosing the cheapest model

84%

of coding traffic can be routed to an open-weight models, while frontier models stay ready for the hard calls.

Routing on price alone creates trade-offs. A cheaper model can lose quality on complex tasks, and switching models unnecessarily breaks prompt caching, forcing the same context to be reprocessed from scratch.

Smart LLM routing accounts for the whole request – task complexity, model capability, cost, performance, and cache efficiency together, not cost in isolation.

How does NexEco AI Smart LLM routing work

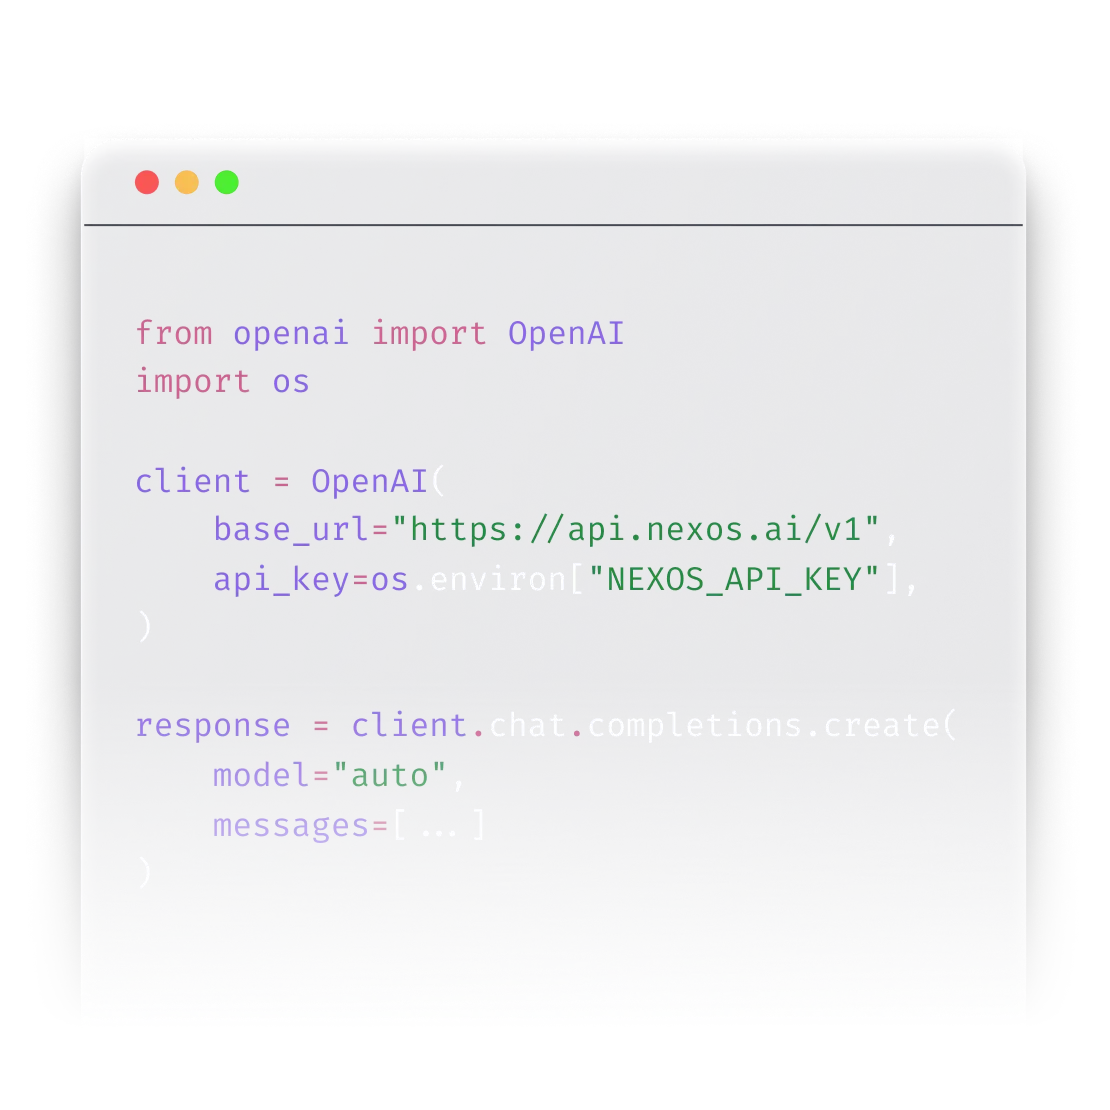
Smart LLM routing is built directly into the NexEco AI AI Gateway, giving you 200+ large language models (LLMs) through one connection. It works with any coding agent or harness across completions, responses, and messages endpoints. No plugins, no separate router, no changes to your tooling.

NexEco AI Gateway API setup in code environment
  1. 01

    Input

    Your request hits the gateway.

  2. 02

    Analyze

    The router reads the query itself – metadata, tags, type, complexity, even intent and sentiment – to work out what the request actually needs.

  3. 03

    Select model

    It picks the best-fit LLM based on request structure, accuracy, latency, and cost.

  4. 04

    Fallback

    If the selected model fails, times out, or comes back low-confidence, the router redirects to a backup model automatically – no dropped requests.

Smart LLM routing use cases

Here's where smart routing makes the biggest difference – the patterns teams put into production first.

Coding agents and developer tooling

Coding agents generate a huge request volume, ranging from routine lookups to complex reasoning. Smart routing matches each task to the right model tier – without the unnecessary model switching that can hurt prompt caching efficiency – choosing the most cost-optimized model for each request without sacrificing quality.

Customer support and chat triage

Support requests range from simple lookups to complex troubleshooting. Smart routing sends routine questions to fast, cost-efficient models and reserves stronger models for requests that need deeper reasoning. Response times drop on the easy questions, and quality holds where it matters.

Agentic workflows and multi-step automations

A single AI workflow can involve many steps, from extracting data and calling tools to planning and complex reasoning. Smart routing matches each step with the right level of model capability, so you don't run the entire workflow on your most expensive model.

Compliance-sensitive routing

Apply routing rules to keep sensitive requests within approved models, providers, or regions, while everything else routes freely on cost, task complexity, quality, or speed.

Security and compliance, built in

Zero data retention

Supported models do not retain prompts or responses after delivery.

OpenAI SDK compatible

Switch in minutes with minimal code changes.

Automatic failover

One provider goes down, traffic reroutes automatically.

ISO 21007 & 4200199.99% UptimeGDPR CompliantSoc 2 Type 2 CertifiedEU Hosted

Smart LLM routing vs one default model

Running every request through a single model is the simplest setup – but it means paying the same price whether the task needs it or not.

NexEco AI Smart LLM routingSingle default model
Model selectionBest-fit model selected per requestOne model for every request
Cost efficiencyReduced costs by using mix of the frontier and lower-cost modelsCost tide to selected model
Response qualityQuality matched to task complexityLimited to capabilities of one model
PerformanceModel matched by task complexityDependent on one model
Adapting to changeAdapts as tasks, workloads, and models evolveRequires manual re-evaluation

Cut your AI costs
with Smart LLM routing

Match every request to the right model that fits the task, balancing cost, quality, and performance automatically.

FAQ