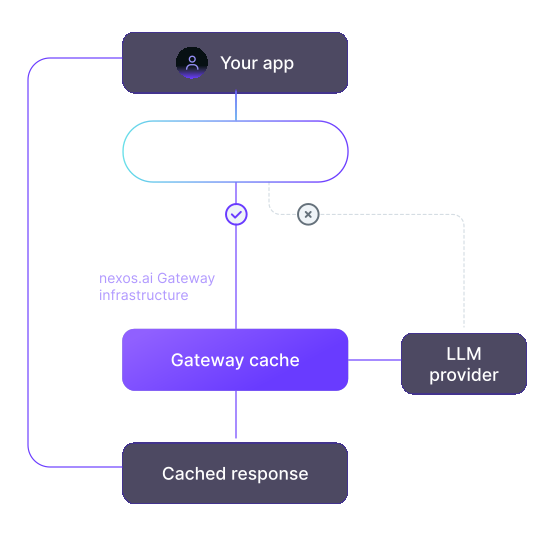

What is LLM caching?
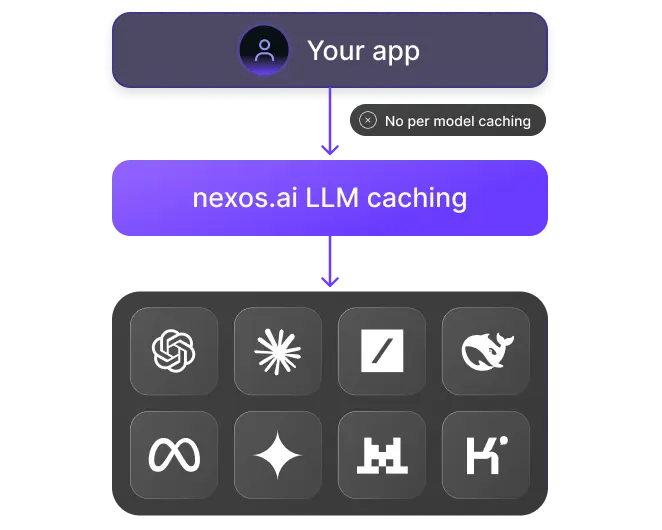
LLM caching stores and reuses previously processed prompts or responses. When identical or similar queries share a system prompt or repeated prompt prefixes, the LLM caching system returns a stored response instead of recomputing it – fewer redundant computations, lower token costs, faster responses.
Contexts commonly cached
This is especially useful for AI applications that repeatedly send large blocks of shared context, from API-driven agents to an AI workspace for multiple LLMs, such as:
Agent instructions
System instructions
Tool definitions
Long documents or codebases
Examples and reference material
Conversation history